What is a text-to-speech (TTS) VTuber?
- Voice Protocol
- Systems
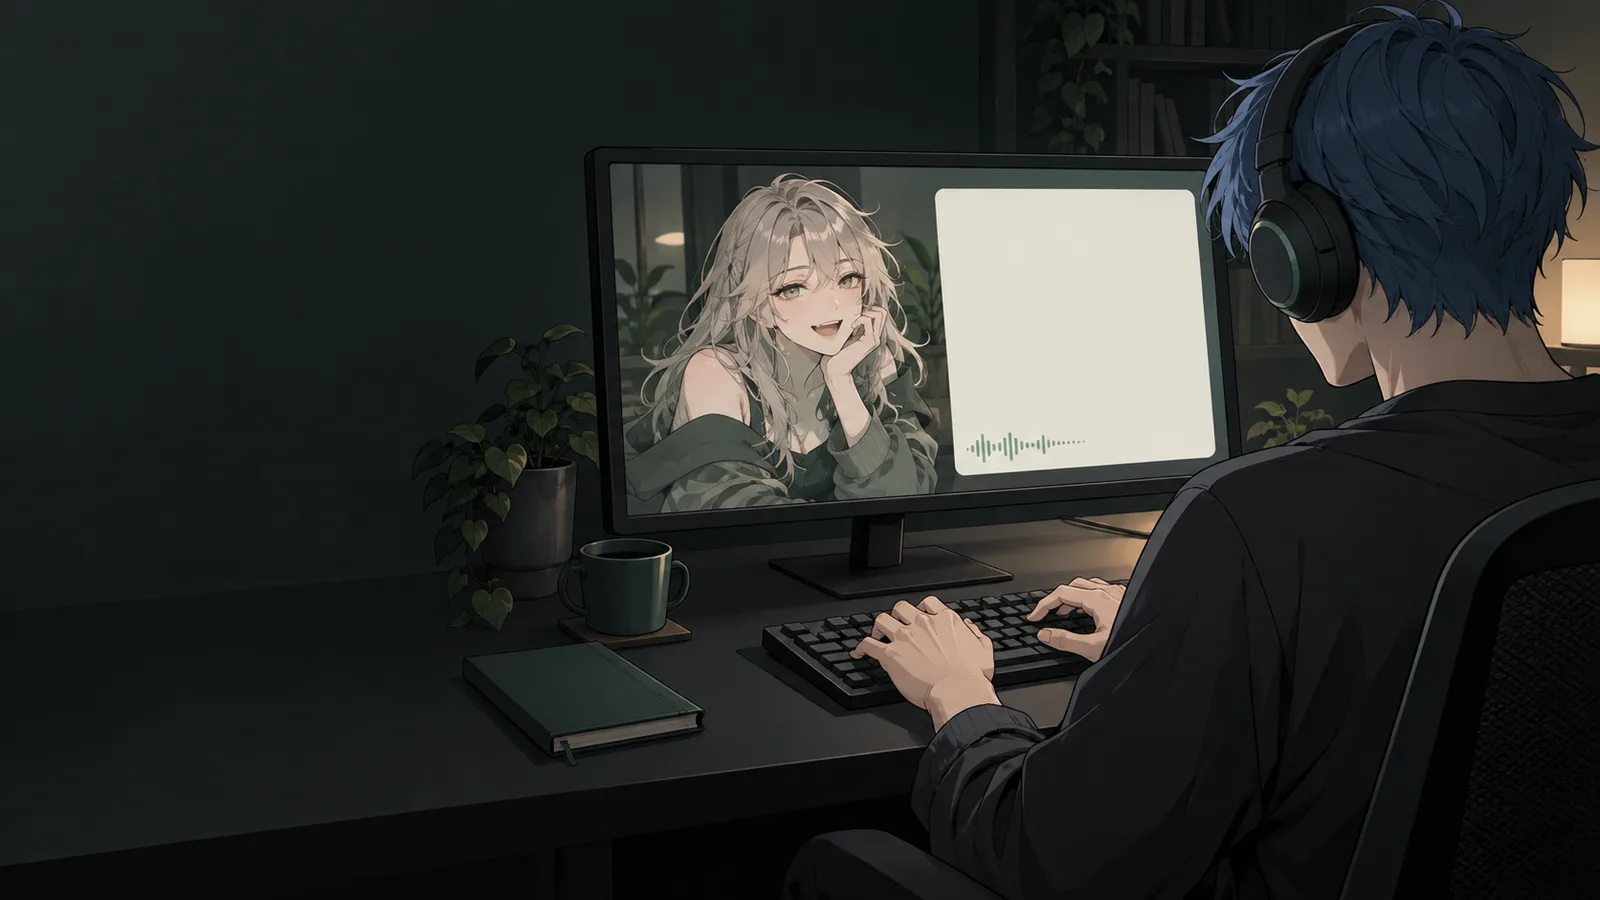
A TTS VTuber is a VTuber who uses text-to-speech to produce some or all of the voice they use to communicate with viewers. The creator may type their messages, speak into a transcription system, or supply text through another input method.
TTS describes how the sound is made. It does not tell you whether the creator can speak, whether they type every line, or whether software writes the dialogue.
To understand a setup, ask three questions: Who supplies the words? How do those words enter the system? What reaches the audience?
What are the different TTS VTuber methods?
| Method | Where the message comes from | What viewers receive |
|---|---|---|
| Typed TTS | The creator types text | Synthetic speech |
| Speech-to-text-to-speech | The creator speaks, and software transcribes the words | Synthetic speech based on the transcript |
| Voice conversion | The creator speaks into an audio-processing system | Transformed speech |
| On-screen text | The creator enters written messages | Readable text |
| Chat text | The creator types directly into the stream chat or a Discord channel | Text in the platform chat |
| Soundboard | The creator selects a prepared audio clip | Recorded speech or sound |
| Viewer chat TTS | A viewer submits a chat message or donation alert | The viewer’s message read aloud |
| AI-generated dialogue with TTS | A system generates the words | Synthetic speech reading those words |
These are descriptions of methods, not exclusive categories of people. A creator can use more than one during the same stream.
Each method adds delay in a different place: the time it takes to type, the wait for transcription, and the moment the voice is generated.
How does typed TTS work?
With typed TTS, the creator composes a message and sends it to a speech engine. The engine produces the audio.
Typed message → speech synthesis → spoken output
For example, you might type “I absolutely meant to do that” after falling off a platform. The synthetic voice delivers your line. You chose the words and the moment to send them.
Typing is one way to supply text. Selecting a saved phrase or using an alternative text-entry device can also feed a speech engine. “Uses TTS” therefore does not establish that someone is typing on a keyboard.
The W3C’s speech-synthesis specification describes text becoming spoken output, with controls for aspects such as pronunciation, rate, and pitch. Which controls a creator can actually use depends on the application and voice.
For live performance, the practical questions include how you enter a line, when it starts playing, and whether you can stop it when the conversation moves on.
Speech-to-text-to-speech: you speak, another voice delivers the words
Speech-to-text-to-speech adds a transcription stage before synthesis. You may see it shortened to STT→TTS, STTTS, or STTS.
Spoken input → speech recognition → text → speech synthesis
The creator speaks into a microphone. Speech recognition identifies the words, and a synthetic voice reads the resulting text. The audience can hear the synthesized output without receiving the original microphone audio, provided the audio routing is configured that way.
This still requires spoken input. Someone looking for a way to communicate without speaking needs a different input method, such as typing.
It also introduces a distinct place for errors: speech recognition may transcribe a different word from the one the creator intended. That is different from correctly entered text being pronounced unexpectedly by the TTS voice.
Zentreya is one of the best-known VTubers using this setup. Her talent profile lists speech-to-text-to-speech as her method, so her synthetic voice starts with her speaking, not with a keyboard. It’s a good reminder that TTS VTubers don’t all type everything.
What gets lost in transcription?
Speech-to-text-to-speech adds a step that typed TTS does not have. Software has to guess what you said before the voice reads it. Names, slang, game terms, and fast speech are the usual misses, and the voice reads the wrong word with full confidence. Some creators make it part of the show. Zentreya plays transcription mistakes for comedy (PANORA), and RIA’s stream descriptions warn viewers that recognition errors sometimes swap her words (YouTube). With typed TTS you pick every word, but typing takes time.
Typed TTS begins with a typed message. Speech-to-text-to-speech begins with spoken input and transcription. Both produce synthetic speech.
Typed TTS
Reading order: Typed message, then Speech synthesis, then Synthetic speech.
Speech-to-text-to-speech
Reading order: Spoken input, then Speech recognition, then Text, then Speech synthesis, then Synthetic speech.
Voice conversion: the input is already speech
Voice conversion transforms speech audio into a different vocal sound. It is one technology associated with products described as “voice changers.” The broader phrase “voice filter” can also include simpler effects such as pitch shifting.
Spoken input → voice conversion → transformed speech
The technical distinction is the input used to produce the output. TTS starts from text, but voice conversion starts from speech. The UnifySpeech research paper explicitly distinguishes those two tasks.
A conventional voice-conversion workflow does not require the speech-recognition-to-text stage used in STT→TTS. Implementations vary, so a product’s marketing label alone is not enough to determine its internal process.
For a creator, this means the spoken performance supplies material for the transformation. It does not guarantee that every breath, inflection, or emotion will be preserved perfectly.
Is voice conversion TTS? Not by itself. Both can change the voice viewers hear, but they work from different inputs.
Speech-to-text-to-speech converts speech into text before synthesis. Voice conversion transforms speech audio without requiring that transcription stage.
Speech-to-text-to-speech
Reading order: Speech, then Recognized text, then Speech synthesis, then Synthetic speech.
- Speech
- Recognized text
- Speech synthesis
- Synthetic speech
Voice conversion
Reading order: Speech audio, then Voice conversion, then Transformed speech. This conceptual path contains no transcription stage.
- Speech audio
- Voice conversion
- Transformed speech
No transcription stage required.
A human using TTS is not automatically an AI VTuber
A speech engine may use machine learning to generate audio. That does not mean it decides what the performer says.
When a person writes a line and TTS speaks it, the person supplies the dialogue. When a system generates a reply and sends it to TTS, software supplies the dialogue too.
Human-written text → TTS and AI-generated text → TTS can share an output technology while having different authors.
The official Neuro-sama and Evil Neuro site identifies those characters as AI VTubers. Their classification should not be transferred to another creator merely because the voice sounds synthetic.
An AI-themed character design is not proof of AI-generated dialogue either. A robot avatar, fictional computer persona, or digital-lifeform backstory describes the character. Understanding the workflow requires separate information.
There are also mixed cases, such as a human reviewing or editing a generated suggestion before speaking it. Describe that actual process when it matters rather than assuming the sound reveals it.
A person can write the text sent to a speech engine, or a system can generate it. Both routes can produce synthetic speech.
Human-written dialogue
Reading order: Person writes a line, then TTS, then Synthetic speech.
- Person writes a line
- TTS
- Synthetic speech
AI-generated dialogue
Reading order: System generates a line, then TTS, then Synthetic speech.
- System generates a line
- TTS
- Synthetic speech
Viewer TTS and the creator’s voice are different uses
A stream can read chat messages, donations, or alerts aloud while the host speaks through an ordinary microphone. In that setup, TTS voices the audience’s contributions. Those features are commonly bundled into streaming and TTS tools, which makes it easy to confuse audience TTS with a creator using TTS to communicate.
That is different from a creator using TTS to deliver their own commentary.
To distinguish them, follow the message. Did the host compose it? Did a viewer submit it? Did software generate it? Hearing synthesized audio somewhere in a stream does not answer those questions.
Some creators also give a pet, mascot or sidekick a TTS voice to banter with. That character is a co-star, not the creator’s own communication method.
Live TTS versus prerecorded narration
TTS can produce a finished voiceover for an edited video or deliver messages during a live stream. The speech-generation technology may be the same, but the timing and workflow differ.
For prerecorded narration, you can write a script, generate takes, and edit the audio before publishing. Live communication requires a way to enter and deliver messages as the conversation unfolds. A tool that exports a voiceover file does not, by that feature alone, provide a live communication setup.
A prerecorded TTS clip can also be triggered during a live stream. That is prepared audio playback, rather than a newly composed message being synthesized in the moment.
Text, soundboards, and mixed setups
An on-screen text bubble does not require speech synthesis. It can carry the creator’s words visually. Chat text skips both the voice and the overlay. The creator types straight into the stream’s chat, so viewers watching full screen or in a clip may miss it unless chat is shown on stream.
A soundboard plays prepared audio. A clip may contain recorded speech, synthesized speech, music, or a sound effect. Triggering it is a separate action from composing a new TTS message.
You can combine those methods. A quick expression might carry a reaction, a prepared phrase might handle a familiar joke, and a longer typed line might explain what happened.
Mizuzu Neo’s 2023 interview with VTuber NewsDrop documents written interaction, chat bubbles, and later experiments with TTS. It is an example of methods changing within one creator’s practice, not a required progression for other creators.
Does “TTS VTuber” mean “mute VTuber”?
No. TTS describes a voice-production method. “Mute” is a description some creators use for themselves. One does not establish the other.
A person who cannot speak can use text input to produce synthesized speech. A person who can speak can also choose that method. A mute creator may communicate through on-screen text or chat text without using TTS at all.
Use the creator’s preferred label, and describe the communication method separately when it is known. Neither a synthetic voice nor an absence of microphone speech is enough to infer a diagnosis or motivation.
That separation also leaves room for a creator to change their setup without someone else deciding that their identity has changed.
What to look for in a creator’s setup
If you want to understand or describe a workflow, these details are more useful than a software name alone:
- Input: typed messages, spoken input, selected phrases, or another method.
- Processing: synthesis, transcription followed by synthesis, voice conversion, or playback.
- Delivery: stream audio, call audio, on-screen text, chat text, or a combination.
- Control: how the creator sends, edits, interrupts, or replaces a message.
A concise description could be: “I type my commentary, a synthetic voice reads it, and the same text appears beside my avatar.” Another could be: “I speak into transcription software, and viewers hear the synthesized result.”
Those are illustrative descriptions, not claims about particular creators. If all a public bio says is “TTS,” the input method may simply be unknown.
Frequently asked questions
Does a TTS VTuber type everything?
No. Some type, and others use speech-to-text-to-speech or saved phrases.
Is a TTS VTuber the same as a mute VTuber?
No. TTS is how the voice is produced, but mute is a label some creators use for themselves.
Is voice conversion TTS?
No. Voice conversion transforms spoken audio, while TTS starts from text.
Are TTS VTubers AI?
Not unless software writes the words.
To try these methods yourself, read Can you be a VTuber without talking?. To find creators using them, browse the Voice Protocol directory.
Related methods
Related posts
- Oct 17, 2026
- Culture
What's your Voice Protocol?
- Oct 16, 2026
- People